- Contentassemblyai.com
Building a voice agent with a coding agent: why this approach beats a visual builder
AssemblyAI argues that using a coding agent (e.g., Claude Code) to build voice agents via its APIs is superior to visual builders. The post details a spec-first workflow, cascaded architecture (speech…
- Featureassemblyai.com
Sync HTTP for voice agents: where it helps, and why streaming stays the default
AssemblyAI emphasizes streaming as the default for voice agents but introduces three new Sync API use cases: second-pass transcription for low-confidence turns, audio recovery after WebSocket drops, a…
- Featureassemblyai.com
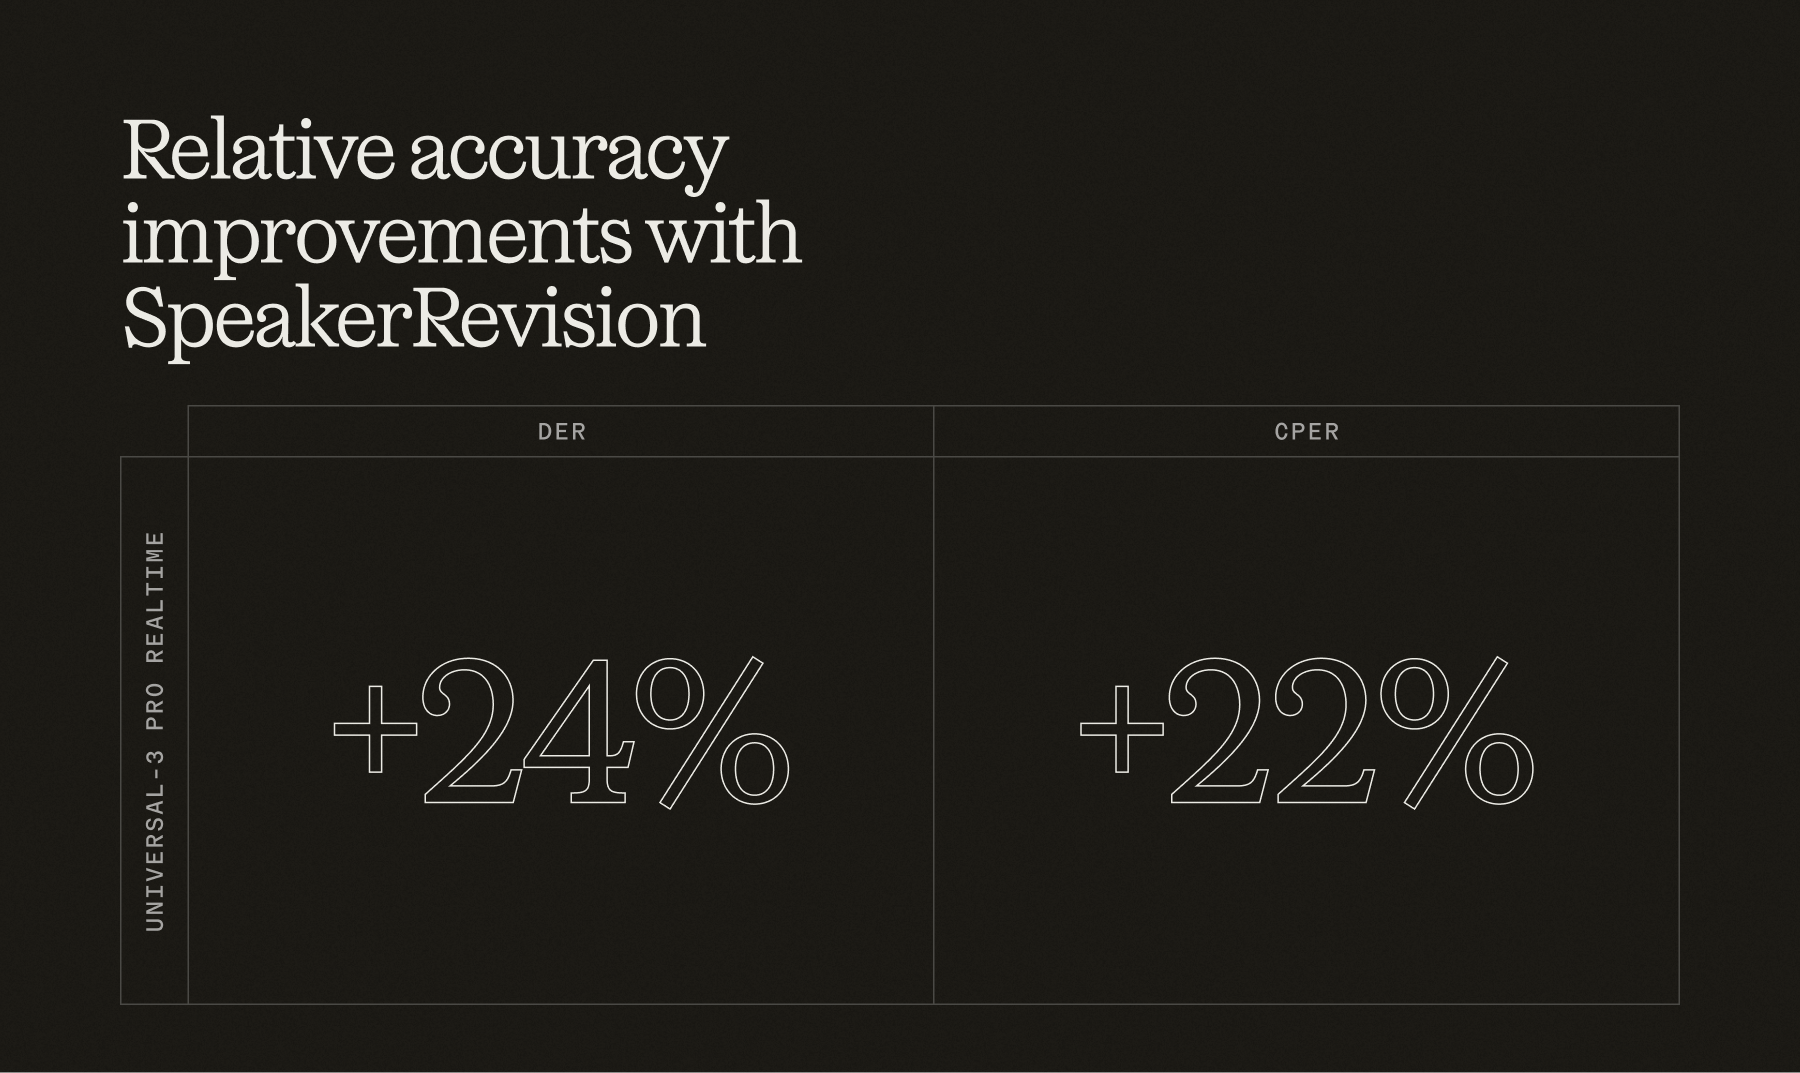
One stream, two jobs: introducing SpeakerRevision
AssemblyAI introduced SpeakerRevision, a feature that revises speaker labels at the end of a live stream using full-context analysis, achieving async-grade accuracy (~30.31% cpWER) with only ~400ms ad…
- Featureassemblyai.com
Best Fish Audio alternatives for text-to-speech in 2026 (including ElevenLabs)
AssemblyAI published a competitive comparison positioning its AssemblyAI-TTS-1 model as a superior Fish Audio alternative for voice agents, emphasizing unlimited concurrency, faster first-audio latenc…
- Contentassemblyai.com
Claude Opus 5.5 vs GPT-6 Astra vs Gemini 4 Argon: which LLM wins on voice data?
AssemblyAI published an October 29, 2026 benchmark of three flagship LLMs on call transcripts, scoring summarization, extraction, correction and dictation alongside cost per audio hour and latency. Cl…
- assemblyai.com
AssemblyAI updates TTS API with streaming and WebSocket support
AssemblyAI expanded its Text-to-Speech (TTS) API with a Streaming TTS feature that synthesizes audio in real-time and returns it via WebSocket for voice agents. The update includes new SDK versions (P…
- Launchassemblyai.com
How to build a voice agent with AssemblyAI: streaming STT, LLM, and TTS
AssemblyAI now offers a unified voice agent stack with Universal-3.6 Pro Realtime for streaming speech-to-text, LLM Gateway for tool-calling LLMs, and Text-to-Speech, all accessible via a single API k…
- Integrationassemblyai.com
Build a production voice agent with LiveKit and AssemblyAI
AssemblyAI and LiveKit launched a production-ready integration enabling developers to build multi-user voice agents in ~100 lines of Python. LiveKit handles WebRTC transport and orchestration while As…
- Integrationassemblyai.com
Build an Agora voice agent with AssemblyAI speech-to-text and text-to-speech
AssemblyAI announced a new integration with Agora’s RTC platform, enabling developers to build server-side voice agents that transcribe, process via LLM Gateway, and respond with text-to-speech—all us…
- Featureassemblyai.com
Build a raw WebSocket voice agent: streaming STT, LLM and TTS with no SDK
AssemblyAI introduced raw WebSocket support for Universal-3.6 Pro Realtime and Text-to-Speech, allowing developers to build voice agents without SDKs. The update includes streaming STT, LLM Gateway in…
- assemblyai.com
Build a real-time voice agent in Python with tool calling
AssemblyAI introduced tool calling for real-time voice agents in Python, allowing developers to build agents that listen, call custom Python functions, and respond via text-to-speech using a single AP…
- Featureassemblyai.com
How to create an AI cold-calling agent with AssemblyAI
AssemblyAI published a guide to building an AI cold-calling agent using their Universal-3.6 Pro Realtime, LLM Gateway, and Text-to-Speech services. The agent qualifies prospects via structured scripts…
- assemblyai.com
Best LLMs for Extracting Structured Data from Transcripts (JSON Output, Speed, and Cost)
AssemblyAI published a detailed analysis ranking over 50 LLMs on their Gateway platform for extracting structured data (participants, action items, decisions, entities) from spoken transcripts of vary…
- assemblyai.com
Best ElevenLabs alternatives for AI phone agents (2026): what to switch to and what changes
AssemblyAI published a detailed guide comparing its AssemblyAI-TTS-1 model against ElevenLabs for AI phone agents, emphasizing superior entity accuracy (93.7% vs 93.6%), native 8 kHz μ-law support, an…
- assemblyai.com
Best LLM for Summarizing Transcripts: From 30-Second Voicemails to Hour-Long Meetings
AssemblyAI introduced Voice Standard Bench to evaluate LLMs for transcript summarization across four transcript lengths (30s to 60m), scoring models on quality, cost per hour of audio, and response ti…
- assemblyai.com
Best LLM for Transcript Correction in 2026: Fix ASR Errors Without Rewriting What Was Said
AssemblyAI introduced a refined approach to transcript correction using LLM Gateway, emphasizing faithfulness to the original speech while improving readability. The company published live benchmarks …
- Contentassemblyai.com
Best LLMs for Dictation Cleanup: Speed, Quality, and Cost, Benchmarked (2026)
AssemblyAI published a 2026 benchmark comparing over 50 LLMs on dictation cleanup tasks, emphasizing latency and exactness over raw quality due to real-time user expectations. The post introduces Voic…
- assemblyai.com
Text to speech vs speech to text: what's the difference and how they work together
AssemblyAI published a detailed guide contrasting speech-to-text (STT) and text-to-speech (TTS), emphasizing their combined role in real-time voice agents. The post highlights AssemblyAI’s Universal-3…
- assemblyai.com
Introducing Universal-3 Pro: A new class of speech language model optimized for Voice AI
AssemblyAI introduced Universal-3 Pro, a first-of-its-kind promptable speech language model optimized for Voice AI applications. The model adapts transcription behavior based on plain-language prompts…

- assemblyai.com
Introducing AssemblyAI-TTS-1: text-to-speech built for voice agents
AssemblyAI introduced AssemblyAI-TTS-1, a text-to-speech API optimized for voice agents with 90ms streaming latency, unlimited concurrency, and a $15 per 1M characters pricing model. The product targe…
- Featureassemblyai.com
How to stream text to speech in Python over a WebSocket
AssemblyAI released new Text-to-Speech API features and Python SDK (v1.8.2) enabling WebSocket-based streaming for voice agents, including real-time LLM token-to-speech conversion, barge-in cancellati…
- Featureassemblyai.com
Building behavioral health documentation that clinicians trust
AssemblyAI introduced Universal-3.5 Pro with Medical Mode for behavioral health transcription, reducing missed medical entities to 3.2% and entity errors by 87% compared to the base model. The update …
- Featureassemblyai.com
Browse LLM Gateway models
AssemblyAI’s LLM Gateway now lists 53 models with updated routing, pricing, and benchmarking. Global routing rates apply, while US/EU endpoints cost 10% more. The Gateway uses its own Voice Standard B…
- Featureassemblyai.com
AssemblyAI adds multichannel transcription with per-channel diarization
AssemblyAI introduced multichannel transcription for pre-recorded audio, enabling separate transcription of each channel in a multichannel file. The feature includes an `audio_channels` property and `…
- Featureassemblyai.com
AssemblyAI upgrades Summarization with topic-based outputs, timestamps, and LLM-driven quality control
AssemblyAI deprecated the top-level `summarization` parameter in favor of a Speech Understanding-based approach, replacing single-block summaries with topic-specific outputs, per-topic headlines, and …
- Featureassemblyai.com
AssemblyAI replaces Auto Chapters with Summarization in Speech Understanding
AssemblyAI deprecated the 'auto_chapters' parameter and replaced it with a new 'Summarization' feature under Speech Understanding, which returns topic summaries with headlines and timestamps. Existing…
- Contentassemblyai.com
How to evaluate TTS for voice agents
AssemblyAI released a four-layer framework to evaluate text-to-speech (TTS) for voice agents, emphasizing entity accuracy (names, numbers, IDs) over generic quality scores like MOS. The guide introduc…
- Featureassemblyai.com
TTS latency explained: time to first audio vs. time to first byte
AssemblyAI published a technical guide distinguishing time to first byte (TTFB) from time to first audio (TTFA) in TTS systems, emphasizing that TTFA is the metric callers experience. The post explain…
- Featureassemblyai.com
Why small LLMs win on short transcripts and lose at meeting length
AssemblyAI published Voice Standard Bench results showing small LLMs (e.g., Qwen3.5 4B Fast) match large models on short transcripts but lag on hour-long meetings, where larger models justify higher c…
- Contentassemblyai.com
How to choose an LLM for production voice tasks
AssemblyAI released a seven-step framework to help companies select the optimal LLM for specific voice workloads, emphasizing per-workload model selection over a one-size-fits-all approach. The guidan…
- Pricingassemblyai.com
AI voice agent pricing in 2026: flat hourly rate vs stacked per-minute costs
AssemblyAI introduced a flat $4.50 per hour (billed per second) pricing model for its Voice Agent API, covering speech, LLM, voice generation, turn detection, recordings, and hosting. The move simplif…
- Featureassemblyai.com
AssemblyAI Voice Agent API adds pre-connect requests for caller lookup
AssemblyAI introduced pre-connect requests in its Voice Agent API, enabling real-time caller lookup via HTTPS endpoints before call answering. The feature allows agents to greet callers by name, retri…
- assemblyai.com
AssemblyAI launches dedicated Dictation service with real-time cleanup and LLM-based rewrites
AssemblyAI introduced a new Dictation service that converts spoken utterances into cleaned-up text in under a second, with both verbatim and LLM-rewritten outputs returned in a single call. The servic…
- Launchassemblyai.com
Voice AI models hosted in your environment
AssemblyAI introduced self-hosted deployment of its Voice AI models, enabling customers to run Universal-3.5 Pro Realtime and Sync APIs on their own infrastructure. The offering delivers lower latency…

- Contentassemblyai.com
What is text to speech? How modern conversational TTS works
AssemblyAI published a technical guide defining text-to-speech (TTS) and highlighting the differences between read-aloud TTS and conversational TTS for voice agents. The post details the neural TTS pi…
- Integrationassemblyai.com
Gemini 4 Argon is now on LLM Gateway: here’s how it scores on voice tasks
AssemblyAI integrated Google’s Gemini 4 Argon model into its LLM Gateway on October 13, 2026, enabling developers to use the model via AssemblyAI’s API for voice-related tasks. Gemini 4 Argon achieved…
- Featureassemblyai.com
Introducing Voice Standard Bench: 50+ models, ranked by performance, speed and cost on real audio
AssemblyAI introduced Voice Standard Bench, a public benchmark scoring 50+ models on AssemblyAI’s LLM Gateway for voice tasks like summarization, information extraction, and text correction. The tool …

- assemblyai.com
Vapi vs LiveKit vs Retell (and Pipecat): Which voice agent stack for production?
AssemblyAI published a detailed guide comparing Vapi, LiveKit, Retell, and Pipecat for building voice agents, emphasizing their different orchestration models and transport layers. The post highlights…
- assemblyai.com
How to cut LLM costs on voice workloads without losing quality
AssemblyAI introduced Voice Standard Bench, a benchmark tool ranking 50+ models on voice-specific tasks (e.g., summarization, extraction) by quality, speed, and cost across transcript lengths. The pos…
- Featureassemblyai.com
Which voice agent API has the best developer experience?
AssemblyAI introduced its Voice Agent API, designed to minimize hidden developer costs by offering a single-WebSocket solution with plain JSON events, live reconfiguration, and bundled speech-to-text,…
- Featureassemblyai.com
What languages does the Voice Agent API support?
AssemblyAI expanded its Voice Agent API to support six languages—English, Spanish, French, German, Italian, and Portuguese—each with native-accent voices. The update allows agents to understand and re…
- Featureassemblyai.com
Build a browser voice assistant in JavaScript with the Voice Agent API
AssemblyAI published a tutorial building a production-ready browser voice assistant in JavaScript using its Voice Agent API, demonstrating conversational turn-taking, barge-in, and gapless playback ov…
- Contentassemblyai.com
Async, sync, or realtime? How to choose the right speech-to-text API
AssemblyAI published a recap of its October 2026 workshop guiding developers on selecting between async, sync, realtime, and dictation speech-to-text APIs. The post outlines a three-question framework…
- assemblyai.com
Best dictation APIs in 2026: 9 options compared for developers
AssemblyAI introduced its Dictation API, designed to return finished text (cleaned of fillers, self-corrections, and punctuated) instead of raw transcripts, addressing a gap in dictation workflows. Th…
- assemblyai.com
How to choose the best speech-to-text API in 2026
AssemblyAI released a comprehensive guide to selecting the best speech-to-text API in 2026, emphasizing benchmarking on real-world audio rather than just WER. The post highlights AssemblyAI’s Universa…
- Launchassemblyai.com
Voice AI infrastructure with unmatched price-performance
AssemblyAI unveiled a new cloud-based voice AI infrastructure platform emphasizing unmatched price-performance, predictable usage-based pricing, and zero infrastructure management. The offering includ…
- Integrationassemblyai.com
Partner with AssemblyAI
AssemblyAI unveiled a growing library of integrations connecting its Speech AI to platforms across voice agent orchestrators, communications infrastructure, meeting bots, no-code automation, and cloud…
Track AssemblyAI on autopilot
- · Weekly AI brief: narrative summary of what shipped, every Monday 9 AM
- · Email or Slack alerts, or chat with the archive in your dashboard
- · Add AssemblyAI + up to 2 more competitors free, no credit card